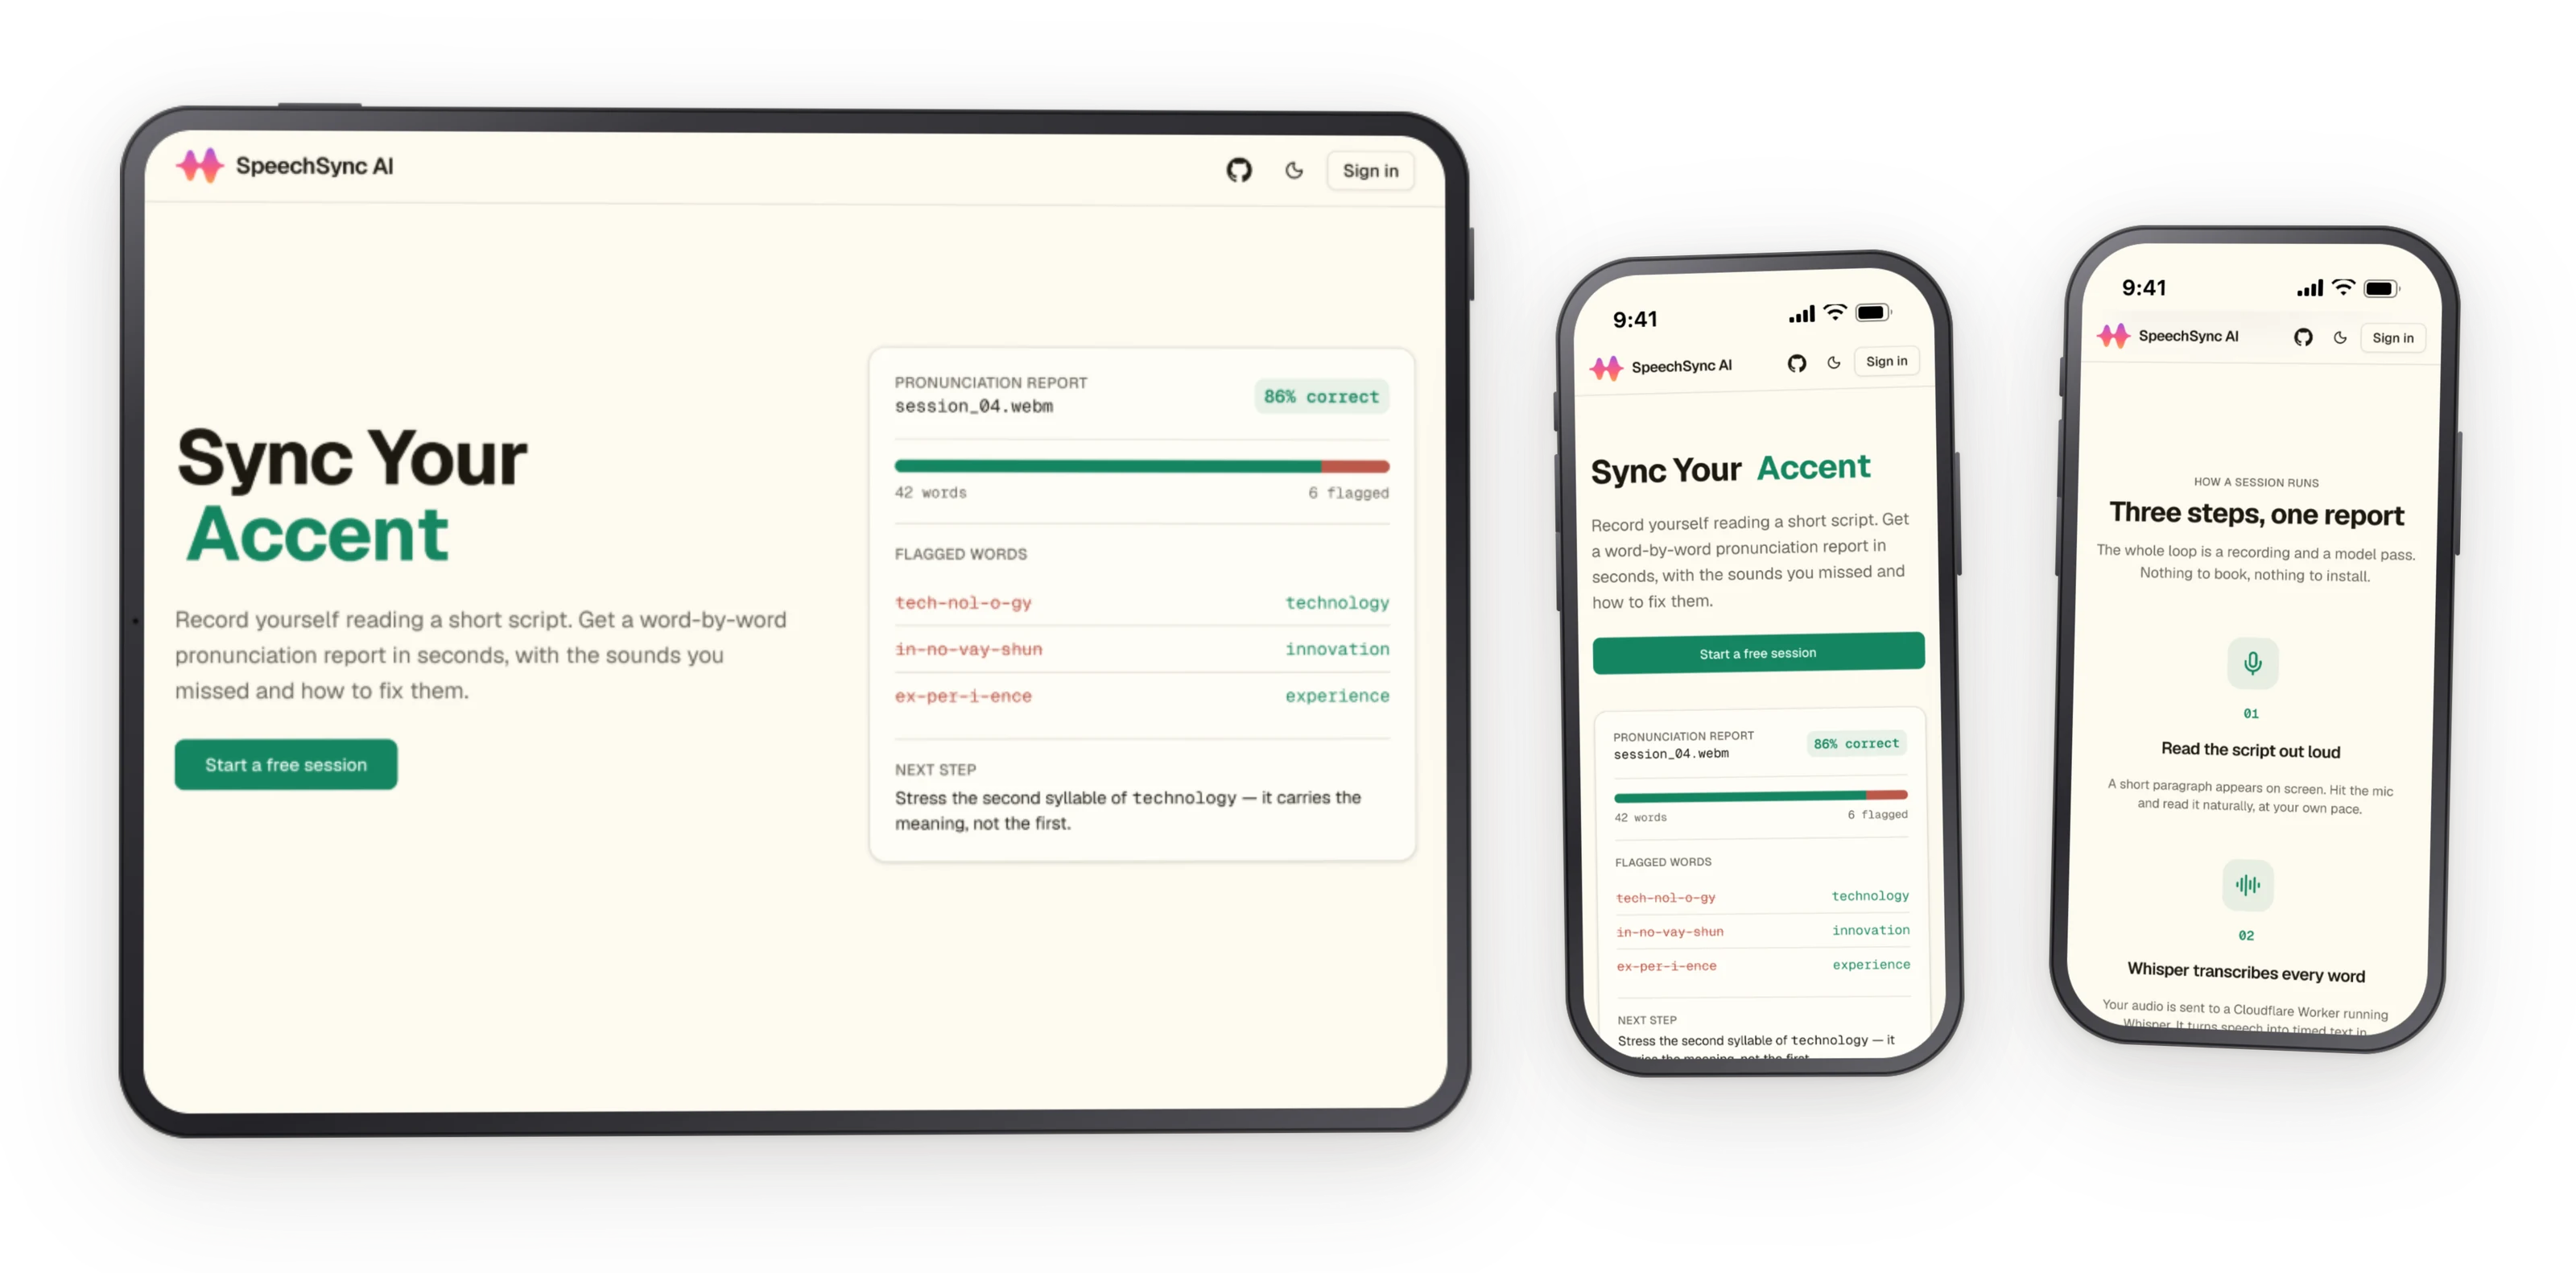
For many international developers, the bottleneck to landing a remote job isn't technical skill, it's pronunciation. You can write flawless code, ace the system design interview, and still get passed over because the hiring manager couldn't understand you on the video call. Traditional language learning apps focus on vocabulary and grammar, which is the wrong abstraction. The problem is phonetic: specific sounds, stress patterns, and intonation that differ between your native language and English.
SpeechSync.ai is a focused tool for this specific problem. Record yourself speaking, and the system runs your audio through Whisper ASR (OpenAI's speech recognition model, running on Cloudflare AI) to get a transcription. Then GPT-3.5 analyzes the transcription against the target text and generates detailed pronunciation feedback: which words were mispronounced, what the correct phonetic pattern should be, and specific exercises to improve.
The architecture is deliberately split: a Next.js 14 frontend handles the recording UI (using React Media Recorder for browser-based audio capture), and a Cloudflare Worker backend handles the AI pipeline. This split matters because the AI inference is compute-heavy and benefits from edge deployment, Cloudflare Workers run close to the user, which reduces latency for the audio upload and transcription step.
The key design decision was using Whisper on Cloudflare AI rather than a third-party transcription API. Cloudflare AI gives you Whisper inference at the edge with no cold starts, which means the transcription step is fast enough to feel real-time. The GPT-3.5 analysis adds a few seconds, but the overall loop, speak, wait, read feedback, is tight enough to be useful for iterative practice.
Built with
Links
Features
- Real-time speech recording, browser-based audio capture with React Media Recorder
- Whisper ASR transcription, OpenAI's speech recognition model running on Cloudflare AI at the edge
- AI pronunciation analysis, GPT-3.5 generates detailed feedback on mispronounced words and phonetic patterns
- Personalized improvement recommendations, specific exercises tailored to your pronunciation patterns
- Edge-deployed inference, Cloudflare Workers minimize latency for audio upload and transcription
- No account required, just open the browser and start practicing
Challenges
The hardest part was making the feedback actionable. It's easy to tell someone "you mispronounced 'algorithm'", it's much harder to explain that they're stressing the wrong syllable (AL-go-rithm vs al-GO-rithm) and give them a specific exercise to fix it. Getting GPT-3.5 to produce consistently useful phonetic feedback required careful prompt engineering with examples of good pronunciation coaching, not just error detection.
What I learned
SpeechSync taught me that the most impactful AI applications aren't the ones that do something impossible, they're the ones that make something expensive accessible. A human pronunciation coach costs $50-100/hour and is available in limited time zones. SpeechSync gives you 80% of that value for free, available 24/7, with infinite patience. The AI doesn't need to be perfect, it just needs to be good enough and always available.